


Hold a key, speak, release — AI voice-to-text dictation that types into any Windows app. Free & open-source.
Cost / License
- Free
- Open Source (GPL-3.0)
Platforms
- Windows


Apps similar to HoldSpeak include Handy STT, which is free and open source. Other options are Vibe Transcribe, Voxtral, FUTO Voice Input and TypeWhisper. There's no shortage of Audio Transcription Tools like HoldSpeak, with more than 100 alternatives for Mac, Windows, the web, iPhone and iPad.
Hold a key, speak, release — AI voice-to-text dictation that types into any Windows app. Free & open-source.
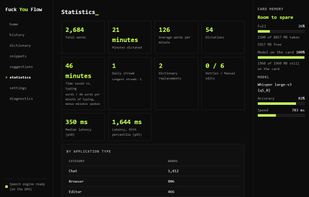
Free offline dictation for Windows and Ubuntu Linux that types what you say into any application, using a Whisper speech model that runs on your own machine.
 Greece
 EU
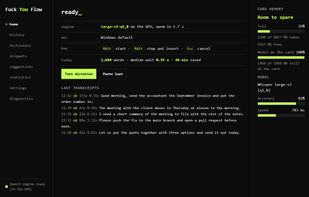
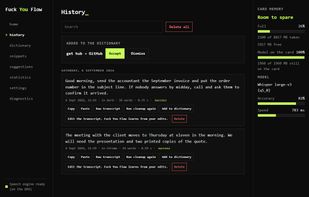
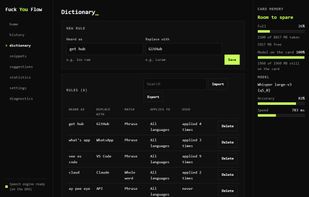

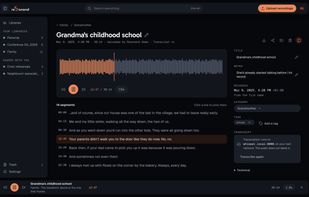
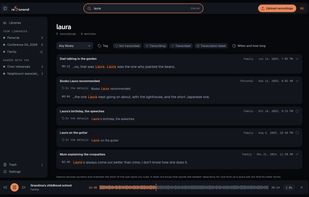
Keeps each recording byte-for-byte, transcribes it through a service you choose, and lets you search inside everything you have.
 SpainEU

On-device voice dictation for Mac. Hold a hotkey, speak, release, and Whisper-transcribed text appears at your cursor. No cloud, no account, no subscription.
 United States
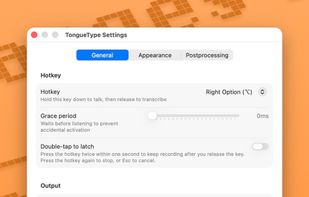
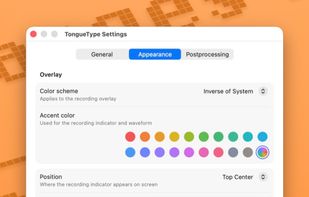
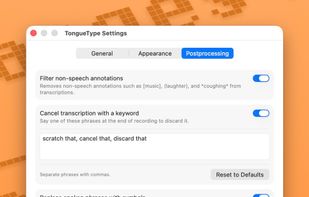

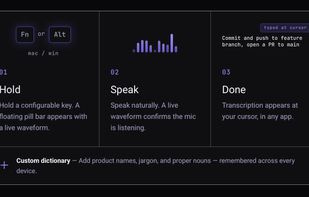
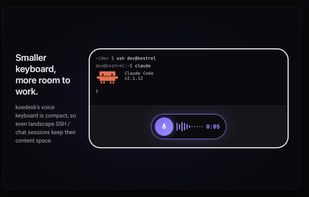
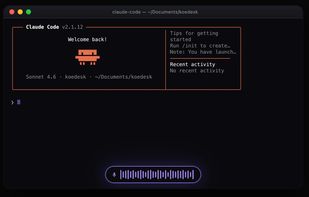
koedesk is a cross-platform voice-to-text tool. Press and hold a key, speak naturally, and your words are typed straight into whatever app you're using — Claude, ChatGPT, Slack, Mail, your editor, anywhere you can type.

Hello Transcribe is a private and secure speech to text transcriber that uses OpenAI Whisper and Whisper.cpp.
 South Africa
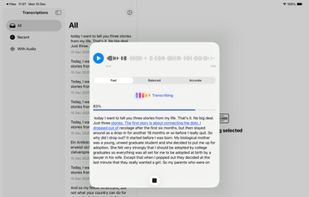


Transcribe audio and video files in a blink, automatically, all offline, and with highly accurate results. AI Transcription uses OpenAI’s Whisper technology and Apple Speech Recognition to convert speech (like in podcasts, presentations, lectures, or voice messages) into text...
 GermanyEU


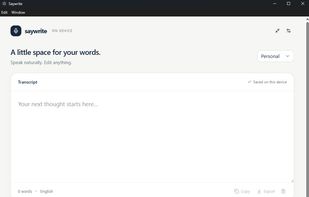
100% on-device, privacy first speech to text desktop app with offline Qwen grammar cleanup.
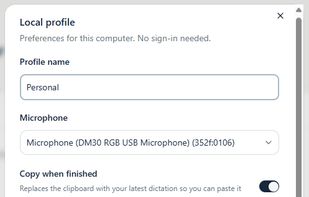

Hold-to-talk speech-to-text for macOS. 100% local, powered by WhisperKit and local LLM cleanup. Hold Control to record, release to transcribe and paste.


A simple transcription service app that records your voice and converts it into text. Use it to quickly transcribe your audio.


VibeVoice is a novel framework designed for generating expressive, long-form, multi-speaker conversational audio, such as podcasts, from text. It addresses significant challenges in traditional Text-to-Speech (TTS) systems, particularly in scalability, speaker consistency, and...
United States


 United Kingdom


