


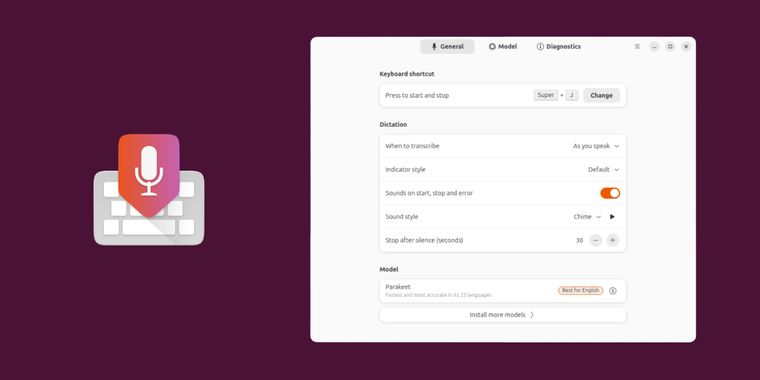

Ubuntu releases Myna voice dictation AI app in technology preview for desktop users
Canonical has officially released Myna, its privacy-focused speech-to-text dictation tool, as a technology preview for Ubuntu desktop users. The project, which draws its name from the speech-mimicking myna bird, marks a significant step forward for local AI-powered accessibility features on the Linux platform. Unlike cloud-dependent dictation services, Myna performs all speech recognition locally on the user's machine, ensuring that audio recordings are neither uploaded nor stored externally once a model is downloaded.
The technology preview is compatible with Ubuntu 24.04 LTS, Ubuntu 26.04 LTS, and Ubuntu 26.10 on amd64 architectures running GNOME under Wayland. Myna supports multiple speech recognition engines, including Parakeet, Whisper, and FunASR, giving users flexibility to choose models based on their language preferences, accuracy needs, and hardware capabilities. For systems equipped with NVIDIA GPUs, the software also offers GPU-accelerated processing to improve performance. Canonical has emphasized that while the core dictation functionality is operational, the project remains under active development and users should expect some rough edges as feedback is gathered from the community.
Installation is straightforward via the command line using an official PPA repository. Beyond usability improvements, Canonical is specifically seeking community input on how Myna performs across different machines, microphones, and languages. The tool is intentionally scoped to dictation purposes only, it does not function as a voice assistant capable of controlling the desktop through voice commands.

- Free
- Open Source
Other apps mentioned in this article

External links
- Myna speech-to-text is now available as a technology previewCanonical • Official source
- Ubuntu's Myna Speech-To-Text Now Available In Tech PreviewPhoronix
- Ubuntu release tech preview of Myna, its AI tool for voice dictationOMG! Ubuntu
- Ubuntu’s Myna Speech-to-Text App Is Now Available as a Technology Preview9to5Linux
- I’ve used Ubuntu for 22 years - and 26.10 might be its best release yetZDNET
No comments so far, maybe you want to be first?