oMLX icon
oMLX icon

oMLX

LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar.
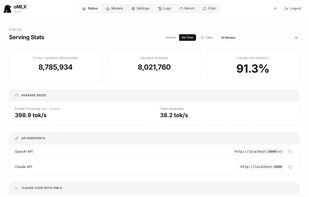
oMLX screenshot 1

Cost / License

Platforms

  • Mac
4likes
0articles
Save

Features

Properties

Features

Highlights All activities

oMLX News & Activities

Recent activities

  • Janus API Router icon
    Paul Tracey added oMLX as alternative to Janus API Router
  • Ollaya icon
    Paul added oMLX as alternative to Ollaya
  • Ben liked oMLX
  • LocalKeep icon
    dcarrero added oMLX as alternative to LocalKeep
  • OptiQ icon
    sandeep85das added oMLX as alternative to OptiQ
  • Voelori icon
    Voelori added oMLX as alternative to Voelori
  • Wierzciu liked oMLX
  • waragdawali liked oMLX
  • Darlene Sonalder liked oMLX
  • Darlene Sonalder added oMLX

oMLX information

AlternativeTo Categories

AI Tools & Services, System & Hardware

GitHub repository

  •  22,732 Stars
  •  2,005 Forks
  •  603 Open Issues
  •   Updated  
View on GitHub

Popular alternatives

View all
oMLX was added to AlternativeTo by Darlene Sonalder on and this page was last updated .

No comments or reviews, maybe you want to be first?

Featured in Lists

My privacy & user friendly setup [2026]

What I use to protect my privacy that I would actually recommand to everyone to try as it does not requiere a lot of effort to use that instead of the GAFAM and Big Brother stuff ! Updated for 2026
By Darlene Sonalder56 appsUpdated

Local LLM, Agent and AI to run on your hardware with no Cloud involved

A list with 25 apps by justarandom without a description.
By Darlene Sonalder25 appsUpdated

Official Links

What is oMLX?

Built for the way agents actually work.

Coding agents invalidate the KV cache dozens of times per session. oMLX persists every cache block to SSD — so when the agent circles back to a previous prefix, it's restored from disk in milliseconds, not recomputed from scratch. 01 — CORE Paged SSD KV caching Cache blocks are persisted to disk in safetensors format. Two-tier architecture: hot blocks stay in RAM, cold blocks go to SSD with LRU policy. Previously seen prefixes are restored across requests and server restarts — never recomputed. 02 — THROUGHPUT Continuous batching Handles concurrent requests through mlx-lm's BatchGenerator. Up to 4.14× generation speedup at 8× concurrency. No more queuing behind a single request. 03 — APP Native macOS menu bar app Start, stop, and monitor the server from your menu bar. Web dashboard for model management, chat, and real-time metrics. Signed, notarized, with in-app auto-update. Not Electron. 04 — MODELS Multi-model serving LLM, VLM, embedding, and reranker models loaded simultaneously. LRU eviction when memory runs low. Browse and download models directly from the admin dashboard. 05 — API OpenAI + Anthropic drop-in Compatible with Claude Code, OpenClaw, Cursor, and any OpenAI-compatible client. Native /v1/messages Anthropic endpoint. Web dashboard generates the exact config command for each tool. 06 — TOOLS Tool calling + MCP Supports all major tool calling formats: JSON, Qwen, Gemma, GLM, MiniMax. MCP tool integration and tool result trimming for oversized outputs. Configurable per model.