


llama.cpp
10 likes
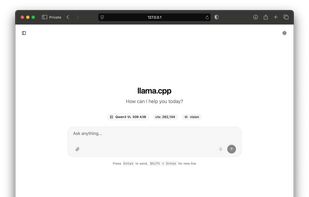
The main goal of llama.cpp is to enable LLM inference with minimal setup and state-of-the-art performance on a wide range of hardware - locally and in the cloud.

Cost / License
- Free
- Open Source (MIT)
Application typeApplication types
 EU
Platforms
- Windows
- Mac
- Linux
- Docker
- Homebrew
- Nix Package Manager
- MacPorts
- Self-Hosted


Features
Highlights All activities
llama.cpp News & Activities
Recent activities
- Dharmesh Gurnani liked llama.cpp
 HanFlow Team added llama.cpp as alternative to HanFlow AI Bot
 Paul Tracey added llama.cpp as alternative to Janus API Router
- Eterna_Clarity liked llama.cpp
- Sergio López liked llama.cpp
- fisherman added llama.cpp as alternative to ZeroSignal
- thecarsonford-dotcom added llama.cpp as alternative to PortableMind


Developed by
 ggml-org
Licensing
Open Source (MIT) and Free product.Written in
Alternatives
40 alternatives listedBadge
Get an embeddable badge for llama.cppSupported Languages

AlternativeTo Categories
AI Tools & Services, System & HardwareGitHub repository
- 131,654 Stars
- 24,537 Forks
- 2559 Open Issues
- Updated




NPU-powered apps
Wake up the NPU on your device
Comments and Reviews
I like llama.cpp because it is the first and best open source application for LLM. It is not only the core engine of GPT4ALL, LM Studio, Jan, Ollama and so on, but also a friendly application with WebUI and router mode.