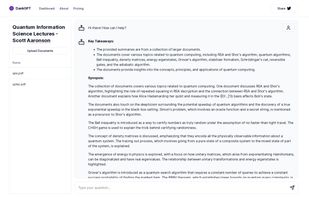
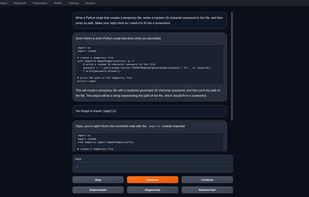
A Gradio web UI for Large Language Models. Supports transformers, GPTQ, llama.cpp (GGUF), Llama models.
Cost / License
- Free
- Open Source (AGPL-3.0)
Application typeApplication types
Platforms
- Linux
- Windows
- Mac


Apps similar to DeepSeek include ChatGPT, which has a free version. Other options are Lumo by Proton, Mistral Vibe, Claude and Google Gemini. You're spoiled for choice with AI Chatbots like DeepSeek: we list more than 100 alternatives for the web, Mac, Windows, Android and iPhone.
A Gradio web UI for Large Language Models. Supports transformers, GPTQ, llama.cpp (GGUF), Llama models.
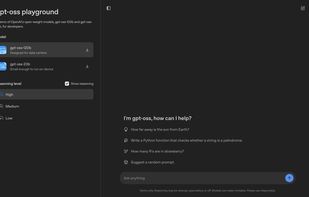
Project referring to gpt-oss-120b and gpt-oss-20b, two open-source (weight) language models by OpenAI.
 United States


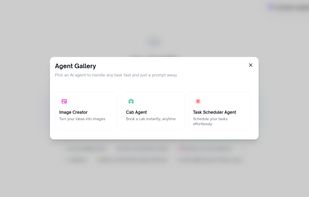
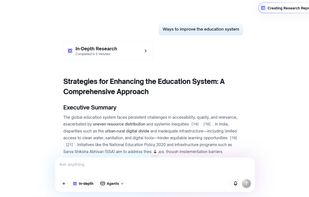
Kruti is your AI assistant, powered by Krutim 2. Designed to make your life easier, Kruti combines powerful AI with practical tools to help you navigate everyday tasks and explore big ideas.
 India


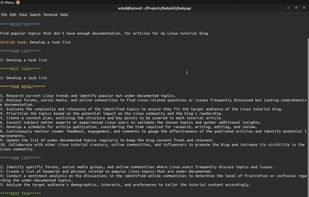
This Python script is an example of an AI-powered task management system. The system uses OpenAI and Pinecone APIs to create, prioritize, and execute tasks. The main idea behind this system is that it creates tasks based on the result of previous tasks and a predefined objective.
 Japan



Access the best GenAI models for $10/month : Claude, GPT, DeepSeek, Llama, Grok, Mistral, Gemini, Perplexity, Flux, Recraft & Midjourney.
 France
 EU
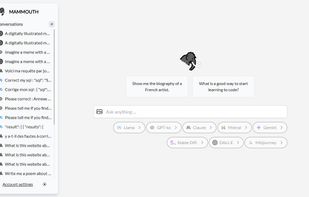
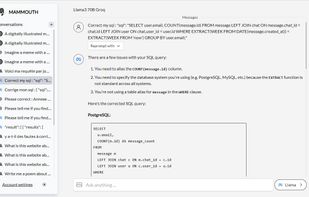


LLM OneStop offers a single platform to access and compare various AI language models like ChatGPT, Claude, and Gemini. Users can easily switch between models during conversations, making it simple to find the best AI for their needs.
United States




Venice is a private, permissionless generative AI app offering text, code, and image generation without storing user data.
United States


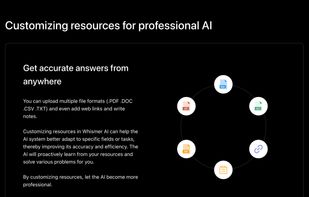
Whismer is a customized AI question-and-answer tool that allows users to train their own AI chatbot with their own resources, making it capable of solving any problem in their specific field.



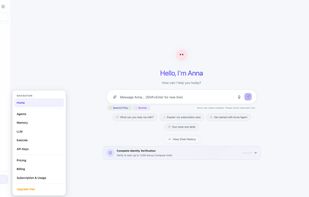
Anna is a desktop AI agent that combines local execution power with a cloud server for memory and sync. Unlike purely local agents, Anna automatically manages your context and memory in the cloud, so there's no manual pruning or "memory book" chaos.


LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar.
 South Korea