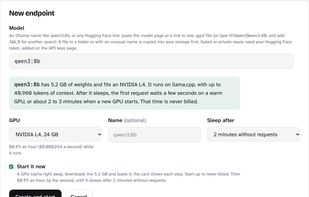
BitsRun turns open AI models into private, OpenAI-compatible API endpoints without renting or managing GPUs. Deploy by name from Ollama (for example qwen3:8b), from a Hugging Face repo (GGUF or safetensors), or from your own upload. BitsRun picks a GPU that fits the model and runs it on llama.cpp, vLLM or Text Embeddings Inference.
Endpoints sleep after an idle timeout you choose (60 seconds to 60 minutes) and wake on the next request. You pay per second only while the model is awake; starting a GPU, loading the model and sleeping are never billed. Credit is prepaid, so there are no surprise bills, and an endpoint can also be kept always on with no cold starts.
Existing code keeps working by changing the base URL and key: OpenAI SDKs, LangChain, LiteLLM, the Vercel AI SDK, Continue and Open WebUI. GGUF endpoints also speak the Ollama API. Prompts and outputs are never logged or used for training. Gated and private Hugging Face repos and LoRA adapters are supported.
BitsRun also makes bitsrun, a free command line and terminal coding agent for macOS, Linux and Windows that deploys models, manages API keys and codes with BitsRun or any other model provider. There is a BitsRun app for Android, and the website and docs are available in English and Spanish.







 Web Bits


No comments or reviews, maybe you want to be first?