See what your local AI is actually doing.
One command, one browser tab. Token-by-token streaming, cache diagnostics, model comparison, benchmarks and cost tracking for the models running on your own machine through Ollama. No cloud. No API keys. No cost.
- Prompt X-ray: the prompt itself, with all it's details and visually clarity.
- Shared box: why Ollama is slow right now, and which tool did it.
- GPU map: what is in video memory, and what models fit.
- Tool calls: can this model drive an agent? Test models against 13 tool cases
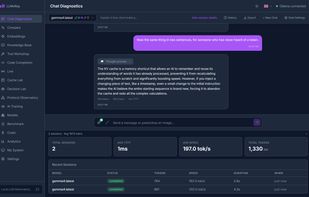
- Chat, token by token analysis, thinking models stream the thinking and full analytics of the chat turns.
- Session deep dive: time to first token, inter-token gaps, the reasoning block if there was one, tool calls, and the exact prompt that was sent.
- Live: what your other tools send, Copilot in VS Code calling local Ollama models, n8n, Open WebUI etc...
- Cache Lab to understand KV cache hit and misses etc...
- Compare: several models with same prompt.
- Protocol Observatory
- Knowledge Base and Embeddings
- Tool Workshop
Also in the box
AI Training Pipeline. Curate pairs from your conversations, tag and review them, export JSONL for fine-tuning.
Local history database. Every chat, comparison and benchmark is archived in IndexedDB with filters, trends, exports and retention rules.
Educators Kit. Nine lesson modules on the docs site, each built around an LLMxRay page.
Five languages. English, French, Serbian (Latin and Cyrillic), Chinese and Arabic, with RTL layout. Scaffolds ready for Hebrew and Japanese.



 EU


 Lognebudo added LLMxRay as alternative to Langfuse, Opik and Open WebUI
 Djovani


No comments or reviews, maybe you want to be first?