




Data Conductor
Like
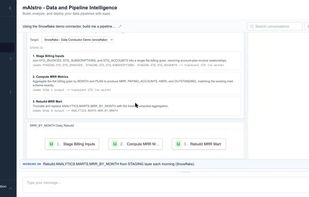
Build and schedule data pipelines in plain SQL across Postgres, MySQL, MS-SQL, BigQuery, Snowflake and Databricks, and move data between databases and cloud storage.

Cost / License
- Subscription
- Proprietary
Since
- New


Features
Highlights All activities
Data Conductor News & Activities
Recent activities
- Andre de Souza added Data Conductor
- Andre de Souza updated Data Conductor
 Andre de Souza added Data Conductor as alternative to Apache Airflow, Kestra, Odara, Windmill Labs and 4 more

Developed by
 Data Conductor
Licensing
Proprietary and Commercial product.Pricing
Subscription ranging between $15 and $100 per month.Alternatives
8 alternatives listedBadge
Get an embeddable badge for Data ConductorSupported Languages


No comments or reviews, maybe you want to be first?