




Email Extract from Documents
Like
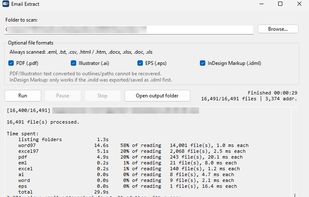
Searches a folder and all its subfolders for e-mail addresses and writes them, with names, into one clean CSV. Reads Word 97 and Excel 97 files that most modern tools no longer open.

Cost / License
- Pay once
- Proprietary
Platforms
- Windows


Features
Email Extract from Documents News & Activities
Highlights All activities
Recent activities
- TschudiTechnologyGmbH updated Email Extract from Documents
- TschudiTechnologyGmbH added Email Extract from Documents
 TschudiTechnologyGmbH added Email Extract from Documents as alternative to FileEmailExtractor-X, FileExtractorPro-X, Extract Emails and Email Extract

Email Extract from Documents information
Developed by
 Tschudi Technology GmbH
Licensing
Proprietary and Commercial product.Pricing
One time purchase (perpetual license) ranging between $5 and $6.Alternatives
3 alternatives listedBadge
Get an embeddable badge for Email Extract from DocumentsSupported Languages


No comments or reviews, maybe you want to be first?