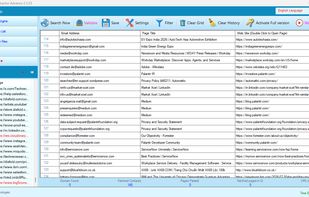
Cute Web Email Extractor is a Windows program that collects publicly available email addresses from websites, search engine results, online PDFs, and local files. Typical uses are outreach lists, recruiter sourcing, and research datasets. Ahmad Software Technologies, active since 2014, develops it.
-AI-assisted keyword research: Supports keyword expansion with ChatGPT and Gemini, plus synonym-enhanced keyword search and email filtering, to find relevant websites and audience-specific phrases, so one idea becomes many searches.
-Bulk URL and Domain Import: Import a bulk list of URLs or domains and set crawl depth, page limits, and per-domain extraction limits to control output volume across large lists.
-Multilingual web crawling and email extraction: Accepts search keywords in multiple languages, including Arabic, Chinese, German, French, and Urdu, to find and crawl regional websites, with country and TLD targeting for regional lead generation.
-Targeting is rule-based. Include and exclude rules on URLs, page content, page titles, and MIME types decide which pages get crawled and parsed, and country and TLD targeting restricts results to chosen regions.
-Two crawl modes cover different sites. Generic crawling reads plain HTML, while browser-based crawling renders JavaScript and AJAX pages, including infinite-scroll content, and has to be enabled for those sites.
-Multi-threading, proxies (HTTP, HTTPS, SOCKS4, SOCKS5), request delays, and automatic resume of interrupted jobs support longer runs.
-Output filters remove duplicates, invalid formats, and image-file false positives, normalize obfuscated addresses, validate domains, and apply custom prefix, suffix, and pattern rules.
-Local mode reads PDF, Word, Excel, HTML, and TXT files on your computer without an internet connection. Results export to XLSX, CSV, or TXT.
-It cannot read addresses inside images (no OCR). Results depend on what sites publish, and lawful use under GDPR, CAN-SPAM, and similar rules is the user's responsibility. It runs on Windows only and does not verify individual mailboxes.






 Ahmad


No comments or reviews, maybe you want to be first?